Professional Big Data Professional Program
Start your big data career from $499. This 16–24 week professional program trains you to architect, manage, and extract actionable insights from massive datasets using Apache Spark, Hadoop, and cloud platforms—with dedicated mentor support and job placement resources.
What You'll Learn
Career-ready skills, mapped to real hiring outcomes.
- Design and implement scalable data pipelines using Apache Spark and Kafka
- Configure Hadoop clusters and manage distributed data processing workflows
- Build real-time analytics systems with stream processing frameworks
- Optimize SQL queries and tune database performance for petabyte-scale datasets
- Deploy data infrastructure on AWS, Azure, and Google Cloud platforms
- Architect end-to-end data solutions from ingestion through visualization
Course Curriculum
5 modules · structured, self-paced.
Module 01 Big Data Foundations & Distributed Systems
- Data fundamentals at scale
- Distributed computing principles
- Hadoop ecosystem architecture
- MapReduce and HDFS deep dive
Module 02 Apache Spark & Real-Time Processing
- Spark SQL and DataFrames
- Streaming with Spark Streaming and Kafka
- Machine learning pipelines
- Performance tuning and optimization
Module 03 Data Pipeline Engineering & ETL
- Design reliable data pipelines
- ETL frameworks and orchestration
- Apache Airflow workflow automation
- Data quality and monitoring
Module 04 Cloud Data Platforms & Data Warehousing
- AWS data services and S3 architecture
- Azure Synapse and Databricks
- Google BigQuery and Cloud Storage
- Modern data warehouse design
Module 05 Capstone: Enterprise Data Architecture
- Design production-grade systems
- Implement security and governance
- Cost optimization strategies
- Present solutions to stakeholders
Who This Is For
Built for these professionals.
- 01 Software engineers transitioning to data roles who want hands-on expertise in distributed systems and pipeline architecture.
- 02 Analytics professionals seeking to move into engineering roles with technical depth in Spark, Kafka, and cloud platforms.
- 03 Database administrators and data warehouse specialists aiming to architect modern, scalable big data solutions.
- 04 Career changers with technical backgrounds ready to specialize in high-demand data engineering positions with competitive salaries.
Common questions about this program.
Do I need Apache Spark or Hadoop experience to start this program?
No. We begin with distributed systems fundamentals and build to advanced Spark optimization. You'll need basic Python or Java skills and some SQL knowledge, but we teach the big data frameworks from the ground up with hands-on labs.
Will this program help me get hired as a Big Data Engineer or Data Architect?
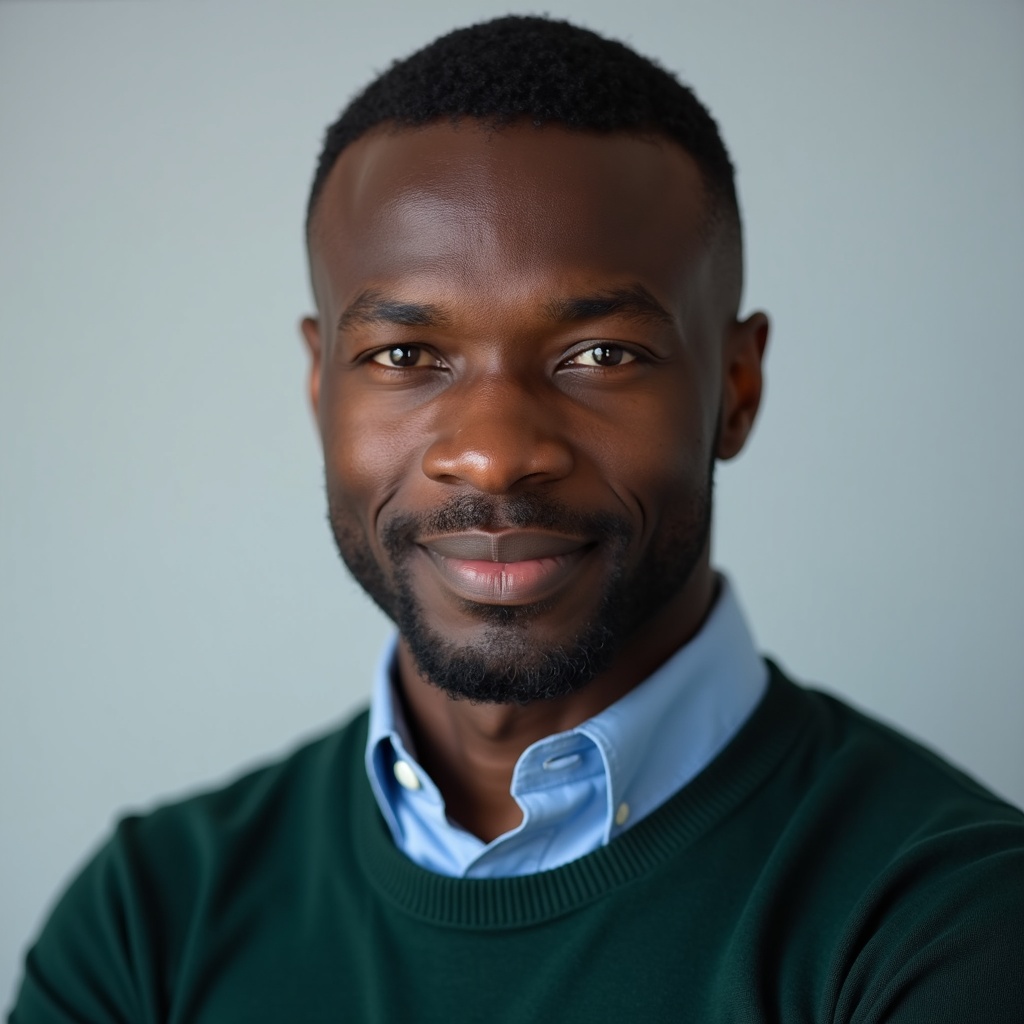
Yes. This professional program includes mentorship from James Okafor, career-focused projects, and a capstone that mirrors real enterprise architectures. We provide job placement resources, interview prep, and portfolio-ready work samples that directly address hiring manager requirements.
What cloud platforms do we use in the curriculum?
We cover AWS (S3, EMR, Glue), Azure (Synapse, Databricks), and Google Cloud (BigQuery). You'll gain hands-on experience deploying pipelines and data warehouses on all three, making you hireable across multi-cloud enterprise environments.
Can I balance this program with full-time work?
Yes. The 16–24 week duration is flexible—you can move faster or slower depending on your schedule. Most students balance this alongside work by dedicating 15–20 hours per week to lectures, labs, and mentorship sessions.
Get Started Today
Ready to start your
big data career?
Enroll now and start building production-grade data systems with direct mentor feedback—your path to Big Data Engineer or Data Architect starts here.